
99 posts tagged with "stackql"

View All Tags

Auditing three clouds without writing three scripts

· 6 min read
Cloud Consultant and AWS Community Builder

If you've audited buckets in more than one cloud, you already know what this is like. Three consoles. Three CLIs. Three auth patterns. And a bit of glue code to pull the outputs together every time someone asks a question that spans all three.

The question is usually simple. "Which buckets are public across all our clouds?" You end up running three separate scripts, then reconciling three different output shapes just to give one answer.

This tutorial doesn't make that faster. It replaces it. One query, one view, all three clouds.

What StackQL is, in three sentences

StackQL is SQL for cloud APIs. You write a normal SQL query, and it makes the API calls to AWS, GCP, Azure, or dozens of other providers to get the answer back as rows and columns.

The important part for this tutorial: it queries the live provider APIs on every run. There's no local database, no cache, no sync job to schedule. What you see is the current state of your cloud, right now.

It exists because someone got tired of writing the same audit logic three times.

What you'll need

You'll need Docker installed and read-only credentials for whichever clouds you want to audit. All three are optional. If you leave a cloud's credentials blank, it gets skipped.

For AWS, GCP, and Azure, the audit needs a service account or role that can list storage buckets and read their configuration. The audit-action repo has the exact permissions per provider here.

Run the audit

The tutorial folder has three files: a docker-compose file, an .env.audit.example template, and a README. Grab the folder from docs/tutorials/preview-bucket-01/ in the stackql/stackql repo.

1. Copy the env template

cp ./audit/.env.audit.example ./audit/.env.audit

Then open .env.audit and fill in credentials for whichever clouds you want. The variables are named for what they are: AWS_ACCESS_KEY_ID, AWS_SECRET_ACCESS_KEY, AWS_REGION, AZURE_TENANT_ID, AZURE_CLIENT_ID, AZURE_CLIENT_SECRET, GOOGLE_CREDENTIALS (the service account JSON, on one line), and GOOGLE_ORG_ID.

If you're only auditing one or two clouds, leave the others blank.

2. Pull the StackQL Docker image

docker compose -f docker-compose.bucket.audit.yaml pull

The tutorial pins to stackql/stackql:v0.10.601. The audit uses views under stackql_preview.* which are still evolving, so pinning matters for reproducibility.

3. Run the audit

docker compose -f docker-compose.bucket.audit.yaml run --rm stackql

On a modest account this takes about 30 seconds. Output goes straight to your terminal as a table.

What the output tells you

When the audit finishes, you get a single table printed to your terminal. Something like this (bucket names are placeholders):
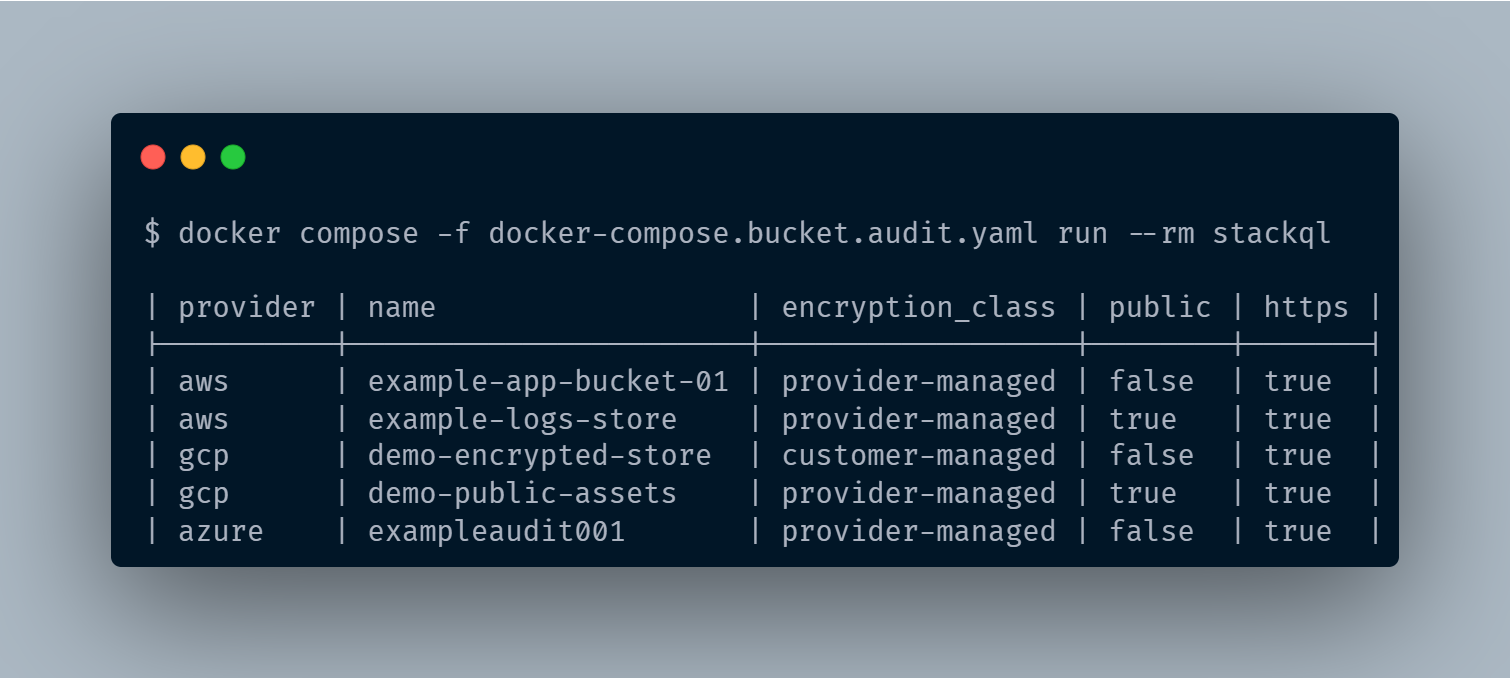
Terminal screenshot showing StackQL audit output as a table with columns for provider, bucket name, encryption class, public flag, and HTTPS enforcement. Rows include AWS, GCP, and Azure buckets with a mix of provider-managed and customer-managed encryption, and one public bucket flagged per AWS and GCP.

Example output from the audit. Bucket configuration across three cloud providers in one normalised table.

The point isn't the specific findings. It's the shape.

Three different resource types (S3 buckets, GCS buckets, and Azure Storage Accounts) normalised into one table with the same columns. Encryption class, public flag, HTTPS enforcement. Side by side, for every cloud you provided credentials for.

A few patterns to notice in the table:

  • Public buckets across providers. Filter by public = true and you have the answer to your security team's question, in every cloud, in one place.
  • Encryption side by side. The encryption_class column shows which buckets use provider-managed keys versus customer-managed. Different providers have different naming conventions internally; StackQL normalises them to the same two categories.
  • HTTPS enforcement in one column. Whether it's S3 bucket policies, GCS uniform access, or Azure secure transfer, same column, same values, no translation needed.

This is what SQL for cloud APIs actually delivers. Not just SQL as a query language, but a uniform data model across providers, so you can ask one question and get one answer.

Performance and scope

StackQL runs each provider's query in parallel using the credentials you provided. There's no local database being populated and no background sync; every run hits the live APIs and returns what's there right now.

On the test account this took about 30 seconds. The query is scoped to one AWS region and one GCP organization, which keeps the API footprint bounded and reflects the current preview default. Streaming output and broader audits (across regions, deeper across resource types) are in flight from the StackQL team.

What this covers today

Today, this audit covers storage buckets across AWS, GCP, and Azure. One region at a time for AWS, one organization at a time for GCP. Entitlements, IAM, and other resource types are on the roadmap as separate audits under stackql_preview.* and will get their own tutorials as they land.

Where to go next

github.com/stackql/stackql is the flagship repo. If this tutorial was worth reading, give it a star. It's genuinely the thing that tells the team to build more tutorials like this one, and it helps other engineers with the same three-console problem find the project.

A few natural next steps from here:

  • Run it against your own accounts. The audit works exactly the same way against real credentials. You can start with one cloud and add the others by adding their env vars.
  • Move it into CI. The stackql-audit-action repo has ready-to-use GitHub Actions workflows for all-clouds, single-cloud, deep-audit, and OIDC-authenticated variants. Drop one into your repo, add secrets, and you have a scheduled cross-cloud audit running on every push.
  • Ask questions. The StackQL community Slack is the fastest way. GitHub issues on the flagship repo also work.

More audits are on the way, including entitlements, deeper checks, and larger estates. If there's a specific one you'd find useful, opening an issue is the fastest way to get it on the roadmap.

New ClickHouse Cloud Provider Available

· 5 min read
Technologist and Cloud Consultant

We've released a new StackQL provider for ClickHouse Cloud:

  • clickhouse - the ClickHouse Cloud control plane (api.clickhouse.cloud): organizations, services (lifecycle, scaling, settings, passwords, private endpoints), API keys, members and invitations, organization roles, backups and backup configuration, usage cost and quotas, activities, ClickPipes, the ClickStack surface (dashboards, alerts, sources, webhooks, saved searches), user-defined functions and Managed Postgres (10 services, 44 resources, 139 operations)

The provider covers the Cloud management API only. The ClickHouse server HTTP interface - SQL against a service endpoint and the system.* tables - is a separate surface with separate authentication and is reserved as a future sibling provider, clickhouse_server. What takes two Terraform providers today (the Cloud infrastructure provider and the DBops provider) will be two namespaces in one StackQL session.

Organization scope from the environment

Every resource except organizations is scoped to an organization. The organization ID is a server variable that StackQL resolves from CLICKHOUSE_ORG_ID when it is set, so queries carry no organization clause:

SELECT name, state, provider, region
FROM clickhouse.services.services;

A WHERE organization_id = '...' still takes precedence when you need to address another organization in the same session. Columns and WHERE/INSERT keys are snake_case (created_at, ip_access_list, service_id); the provider maps them to the API's camelCase on the wire.

Estate inventory

State, footprint and scaling configuration for every service in one result set:

SELECT name, state, provider, region,
num_replicas,
min_replica_memory_gb, max_replica_memory_gb,
json_extract(current_scaling, '$.effectiveAutoscalingMode') AS scaling_mode,
idle_scaling, idle_timeout_minutes, clickhouse_version
FROM clickhouse.services.services
ORDER BY provider, region, name;

Organization quotas report usage against limits, which is the quickest answer to "how much room is left":

SELECT quota_code, name, value AS quota_limit, usage
FROM clickhouse.organizations.quotas;

Usage cost by day and entity

The usage cost endpoint returns one row per entity per day in ClickHouse Credits, with the compute, storage, backup and data-transfer components in a metrics object:

SELECT date, entity_type, entity_name, total_chc,
json_extract(metrics, '$.computeCHC') AS compute_chc,
json_extract(metrics, '$.storageCHC') AS storage_chc,
json_extract(metrics, '$.backupCHC') AS backup_chc
FROM clickhouse.organizations.usage_costs
WHERE from_date = '2026-08-01' AND to_date = '2026-08-31'
ORDER BY date, entity_name;

Joined to the services list, the same data answers which stopped or idle services still carried cost in the window:

SELECT s.name, s.state, SUM(c.total_chc) AS chc_in_window
FROM clickhouse.services.services s
JOIN clickhouse.organizations.usage_costs c
ON c.service_id = s.id
WHERE c.from_date = '2026-08-01' AND c.to_date = '2026-08-31'
AND s.state IN ('stopped', 'idle')
GROUP BY s.name, s.state
ORDER BY chc_in_window DESC;

Scaffolding

Provisioning is the usual SQL verbs. A service is an INSERT; the state command (start, stop, awake) is an EXEC; access-list changes are an UPDATE whose PATCH body takes add/remove arrays, passed through as written:

INSERT INTO clickhouse.services.services
(name, provider, region, min_replica_memory_gb, max_replica_memory_gb, num_replicas, idle_scaling, idle_timeout_minutes)
SELECT 'analytics-dev', 'aws', 'us-east-1', 8, 8, 1, true, 15;

UPDATE clickhouse.services.services
SET ip_access_list = '{"add": [{"source": "203.0.113.0/24", "description": "office"}],
"remove": [{"source": "0.0.0.0/0", "description": "Anywhere"}]}'
WHERE service_id = '<service-uuid>';

EXEC clickhouse.services.services.update_state
@serviceId = '<service-uuid>',
@command = 'stop';

Organizations that use Custom Roles assign API key roles by ID, so the role lookup and the key creation are one statement, and the generated secret comes back with RETURNING:

INSERT INTO clickhouse.keys.keys (name, assigned_role_ids, state)
SELECT 'finops-reader', '["' || id || '"]', 'enabled'
FROM clickhouse.roles.roles
WHERE name = 'Organization API Reader'
RETURNING json_extract(result, '$.key.id') AS id,
json_extract(result, '$.keyId') AS key_id,
json_extract(result, '$.keySecret') AS key_secret;

Backup configuration is queryable across the estate, and settable per service:

SELECT s.name, b.backup_period_in_hours, b.backup_retention_period_in_hours, b.backup_start_time
FROM clickhouse.services.services s
JOIN clickhouse.backups.backup_configurations b
ON b.service_id = s.id;

Observability as code

ClickStack dashboards, alerts, sources, webhooks and saved searches are resources with full CRUD, so a dashboard definition lives in version control and is applied with an INSERT:

INSERT INTO clickhouse.clickstack.dashboards (service_id, name, tiles, tags)
SELECT '<service-uuid>', 'Service Overview',
'[{"name": "Error rate", "x": 0, "y": 0, "w": 6, "h": 3,
"config": {"displayType": "line",
"select": [{"aggFn": "count", "where": "SeverityText = ''ERROR''"}]}}]',
'["production"]';

and audited with a SELECT:

SELECT d.name, json_array_length(d.tiles) AS tiles, d.tags
FROM clickhouse.clickstack.dashboards d
WHERE d.service_id = '<service-uuid>';

Alerts and webhooks follow the same pattern (clickhouse.clickstack.alerts, clickhouse.clickstack.webhooks), and the organization activity log is a table for audit questions:

SELECT created_at, type, actor_type, actor_details
FROM clickhouse.organizations.activities
ORDER BY created_at DESC;

The data platform estate in one query

Cross-provider joins are ordinary SQL, so ClickHouse Cloud services sit alongside Snowflake warehouses and Databricks clusters in one inventory:

SELECT 'clickhouse' AS platform, name, state, region
FROM clickhouse.services.services
UNION ALL
SELECT 'snowflake', name, state, NULL
FROM snowflake.warehouses.warehouses
UNION ALL
SELECT 'databricks', cluster_name, state, NULL
FROM databricks_workspace.compute.clusters
WHERE deployment_name = '<workspace>';

Authentication

Create an API key pair in the ClickHouse Cloud console (Settings -> API Keys) with the role the queries need - Organization API Reader / Service API Reader for inventory and cost queries, Service API Admin for provisioning - and export three variables:

export CLICKHOUSE_CLOUD_API_KEY=... # Key ID
export CLICKHOUSE_CLOUD_API_SECRET=... # Key Secret
export CLICKHOUSE_ORG_ID=... # organization ID

The API allows a fixed window of requests per key (documented as 10 per 10 seconds); a 429 is the signal to pace wide scans.

Get started

Pull the provider from the public registry:

registry pull clickhouse

Provider docs are at clickhouse-provider.stackql.io. Let us know what you build. Star us on GitHub.

Google Provider Update - August 2026

· 3 min read
Technologist and Cloud Consultant

We've released an update to the StackQL Google provider, regenerated from the latest Google API discovery documents. The google provider now covers 187 services, 2,183 resources and over 9,100 operations - up from 179 services, 1,966 resources and 8,423 operations in the previous release. The companion providers in the google family (googleworkspace, googleadmin and firebase) were regenerated in the same pass.

New Services

Eleven services are new in this release:

ServiceDescription
agentregistryCentralized catalog to store, discover and govern MCP servers, tools and AI agents within Google Cloud
agentidentityIdentities and authorization for AI agents - auth providers, authorizations and access summaries
agentidentitycredentialsShort-lived credential issuance for agent identities
cesGemini Enterprise for Customer Experience - agents, apps, deployments, conversations, guardrails and tool schemas
hypercomputeclusterCluster Director - deploy, manage and monitor AI/ML and HPC clusters
databasecenterOrganization-wide database fleet health monitoring across projects and folders
metastoreDataproc Metastore - services, backups, federations, metadata imports and migrations
threatintelligenceGoogle Threat Intelligence - alerts, findings, documents and configurations
cloudnumberregistryIP address management - realms, registry books, custom and discovered ranges
developerknowledgeProgrammatic access to Google developer documentation
healthGoogle Health API (v4) - health and fitness metrics, data points, devices and subscriptions

Expanded Coverage in Existing Services

  • compute - the largest expansion in this release, 73 new resources: capacity planning (future_reservations, reservation_slots, reservation_blocks and reservation_sub_blocks versions), instant_snapshot_groups and regional snapshot resources, cross_site_networks and wire_groups, organization_security_policies, network_firewall_policies, rollouts and rollout_plans, plus per-resource IAM policy resources across addresses, firewalls, health checks, routes, target proxies and more
  • aiplatform (Vertex AI) - agent engine build-out: agents, memory_banks, sandbox_environments (with templates and snapshots), online_evaluators, evaluation_metrics, responses and semantic governance policy resources
  • oracledatabase - GoldenGate integration: deployments, deployment environments/types/versions, connections and connection assignments, plus autonomous database refreshable clones
  • dataplex - universal catalog governance: data_domains, data_products, data_assets, metadata_feeds and change_requests
  • redis - token-based auth: token_auth_users, auth_tokens and acl_policies
  • networksecurity - dns_threat_detectors and Secure Access Connect realms and attachments
  • cloudkms - single_tenant_hsm_instances, key deletion proposals and retired_resources
  • observability - log analytics buckets, datasets, links, views and scope settings

Another 50+ services picked up incremental resources and operations, including discoveryengine, contactcenterinsights, netapp, artifactregistry, assuredworkloads and dataproc.

Removed Services

Google has retired several APIs since the last release, and they are removed from the provider accordingly:

  • datalabeling - AI Platform Data Labeling was shut down
  • integrations - Application Integration no longer publishes a discovery document
  • lifesciences - Cloud Life Sciences was shut down
  • dataplex Explore resources (content, environments, sessions) were removed upstream

The duplicate *_aggregated helper resources in compute were also consolidated - cross-zone queries are served by the primary resources, so a zone-less SELECT fans out across all zones:

SELECT name, status, machineType, zone
FROM google.compute.instances
WHERE project = 'my-project';

Example: Open Firewall Audit

Ingress rules open to the entire internet, and what they allow:

SELECT
name,
direction,
sourceRanges,
allowed
FROM google.compute.firewalls
WHERE project = 'my-project'
AND sourceRanges LIKE '%0.0.0.0/0%';

Get Started

Pull the latest provider from the public registry:

stackql registry pull google;

Authenticate with a service account key in the GOOGLE_CREDENTIALS environment variable (or interactively via gcloud auth login), then explore:

SELECT
json_extract(config, '$.name') AS api,
state
FROM google.serviceusage.services
WHERE parent = 'my-project'
AND parentType = 'projects'
AND filter = 'state:ENABLED';

Provider docs, including getting-started queries for each provider in the family, are at google-provider.stackql.io, googleworkspace-provider.stackql.io, googleadmin-provider.stackql.io and firebase-provider.stackql.io. Visit us on GitHub and let us know how you're using it.

New Google Gemini Provider Available

· 3 min read
Technologist and Cloud Consultant

We've released a new StackQL provider for the Google Gemini API:

  • gemini - the Generative Language API surface (generativelanguage.googleapis.com): inference (content generation, embeddings, token counting, batches) plus the API's own management surface - models, tuned models and permissions, files, cached contents, corpora, file search stores and long-running operations (10 services, 32 resources, 75 operations)

Everything reachable with a GEMINI_API_KEY ships in one provider. Authentication is handled automatically, LIMIT is pushed down to the wire, and paginated lists are walked for you.

Inference as a result set

Asking Gemini a question is a SELECT. The reply comes back as a row, with the text in the candidates array and the token spend in usageMetadata:

SELECT
JSON_EXTRACT(candidates, '$[0].content.parts[0].text') AS reply,
JSON_EXTRACT(usageMetadata, '$.totalTokenCount') AS total_tokens
FROM gemini.models.content
WHERE modelsId = 'gemini-2.5-flash'
AND contents = '[{"parts":[{"text":"Name the four Galilean moons of Jupiter, comma separated."}]}]';

Token counting works the same way via gemini.models.token_counts - free of charge, so a prompt can be priced before it is sent. Embeddings come back as rows too:

SELECT JSON_EXTRACT(embedding, '$.values[0]') AS first_dimension
FROM gemini.models.embeddings
WHERE modelsId = 'gemini-embedding-001'
AND content = '{"parts":[{"text":"stackql lets you query cloud APIs with SQL"}]}';

Which model can do what

The provider ships a convenience view that fans each model's supported generation methods and limits out into flat columns:

SELECT name, display_name, input_token_limit, thinking, supports_generate_content
FROM gemini.models.vw_model_capabilities
ORDER BY name;

One row per model with token limits, default sampling parameters, and boolean flags for content generation, token counting, embedding, batching and caching support - useful for picking a model programmatically instead of reading release notes.

The management surface as SQL

Files, cached contents, corpora, file search stores and tuned models are managed with the corresponding SQL verbs:

-- create
INSERT INTO gemini.corpora.corpora (displayName)
SELECT 'my-knowledge-base'
RETURNING name, displayName;

-- read
SELECT name, displayName, mimeType, sizeBytes, state
FROM gemini.files.files;

-- update
UPDATE gemini.cached_contents.cached_contents
SET ttl = '600s'
WHERE cachedContentsId = 'my-cache-id';

-- delete
DELETE FROM gemini.cached_contents.cached_contents
WHERE cachedContentsId = 'my-cache-id';

Batches are long-running operations and follow the async job pattern: SELECT polls them, EXEC runs the lifecycle ops:

SELECT name, done, JSON_EXTRACT(metadata, '$.state') AS state
FROM gemini.batches.batches;

EXEC gemini.batches.batches.cancel @batchesId = 'my-batch-id';

Tuned model permissions are a full CRUD surface as well, so sharing a tuned model is an INSERT and auditing who can see it is a SELECT.

One credential, one boundary

The provider covers the Gemini API surface under a GEMINI_API_KEY. Billing, quota, API key management and IAM are GCP control-plane services (cloudbilling, serviceusage, apikeys, iam) that authenticate with OAuth/ADC - they live in the google provider. StackQL does cross-provider joins, so the two compose; worked examples are at gemini-provider.stackql.io/google-control-plane.

Authentication

Set a single environment variable:

export GEMINI_API_KEY=...

Keys are created in Google AI Studio. The key is only ever sent as a request header (x-goog-api-key) - never in the URL query string.

Get started

Pull the provider from the public registry:

registry pull gemini

Provider docs are at gemini-provider.stackql.io. Let us know what you build. Star us on GitHub.

Databricks Providers Update - July 2026

· 3 min read
Technologist and Cloud Consultant

We've released an update to the StackQL Databricks providers, regenerated from the latest Databricks platform APIs (SDK v0.123.0):

Includes 392 resources and over 1,200 operations across both providers, including four new services and more than 70 new or restructured resources.

New Services

ProviderServiceDescription
databricks_accountdisasterrecoveryManage disaster recovery failover groups and stable URLs for workspace failover across regions
databricks_workspaceaisearchDatabricks AI Search endpoints and indexes, including data plane operations to query, scan, sync and upsert index data
databricks_workspacebundledeploymentsDatabricks Asset Bundle deployments - deployments, versions, operations and deployed resources
databricks_workspacesupervisoragentsAgent Bricks supervisor agents - agents, tools, examples and permissions

Expanded Coverage in Existing Services

  • postgres (Lakebase) - the largest expansion in this release, now 24 resources covering projects, branches, databases, roles, endpoints, tables, synced tables, catalogs, snapshots, compute instances, change data feed configs and statuses, forward ETL, replication group previews and recovery branch previews
  • iamv2 (account and workspace) - the restructured identity APIs: full lifecycle for users, groups, service_principals, direct_group_members, workspace_access_details, workspace_assignment_details, external_users and transitive_parent_groups, plus account access identity rules and attribute control entries
  • catalog - Unity Catalog AI Gateway services (ai_gateway_model_services, ai_gateway_mcp_services, ai_gateway_agent_services, ai_gateway_model_provider_services), privilege assignments (direct and effective), UC secrets and temporary volume credentials
  • dashboards - AI/BI Genie evaluation runs and results
  • apps - app spaces, app space operations and app thumbnails
  • compute - default base environments for serverless environments and library management
  • vectorsearch - vector search index management and endpoint permissions
  • ml - feature engineering streams
  • billing (account) - usage policies

SQL Statement Execution Improvements

StackQL lets you traverse the Databricks control plane and data plane in the same query surface. This release cleans up the verb mappings for databricks_workspace.sql.statement_execution, so the full statement lifecycle maps naturally to SQL:

/* submit a statement to a SQL warehouse */
INSERT INTO databricks_workspace.sql.statement_execution (
statement,
warehouse_id,
wait_timeout,
deployment_name
)
SELECT
'SELECT * FROM samples.nyctaxi.trips LIMIT 100',
'<warehouse_id>',
'0s',
'<deployment_name>';

/* poll for status and results */
SELECT status, manifest, result
FROM databricks_workspace.sql.statement_execution
WHERE statement_id = '<statement_id>'
AND deployment_name = '<deployment_name>';

/* cancel a running statement */
DELETE FROM databricks_workspace.sql.statement_execution
WHERE statement_id = '<statement_id>'
AND deployment_name = '<deployment_name>';

The cancel operation is now mapped to the DELETE verb (previously INSERT), and sql.query_history now projects one row per query with server-side pagination wired in, so large result sets append across pages automatically.

Built-in Views

Both providers ship with curated views that flatten common multi-step queries into a single SELECT, and this release adds views for Lakebase alongside the existing IAM, billing, provisioning, networking and settings views - 49 views in total. For example:

SELECT *
FROM databricks_account.iam.vw_account_user_roles
WHERE account_id = '<account_id>';

SELECT key, value
FROM databricks_workspace.settings.vw_all_settings
WHERE deployment_name = '<deployment_name>';

Get Started

Pull the latest providers from the public registry:

stackql registry pull databricks_account
stackql registry pull databricks_workspace

Authenticate with the same service principal environment variables used by Terraform and the Databricks CLI (DATABRICKS_ACCOUNT_ID, DATABRICKS_CLIENT_ID, DATABRICKS_CLIENT_SECRET), then explore:

SELECT workspace_id, workspace_name, workspace_status, deployment_name
FROM databricks_account.provisioning.workspaces
WHERE account_id = '<account_id>';

Provider docs are at databricks-account-provider.stackql.io and databricks-workspace-provider.stackql.io. Visit us on GitHub and let us know how you're using it.